From consulting to operations
One-stop delivery of your compute foundation
HYPEX AI delivers end-to-end AI data center capabilities spanning consulting, prefabricated infrastructure, server products, network & storage, O&M, and Compute Token operations — turning compute into an asset that is plannable, deliverable, and operable.
Six modules covering the full lifecycle of an AI data center
From top-level consulting to long-term operations, HYPEX AI combines modular capabilities to fit AI data center builds at every stage.
Consulting & Solution Design
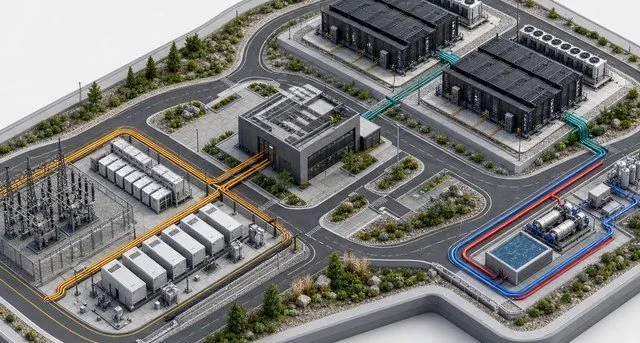
Requirement breakdown, compute planning, digital twin & simulation, standards compliance, and cost estimation — delivered as an actionable build blueprint.
Learn more →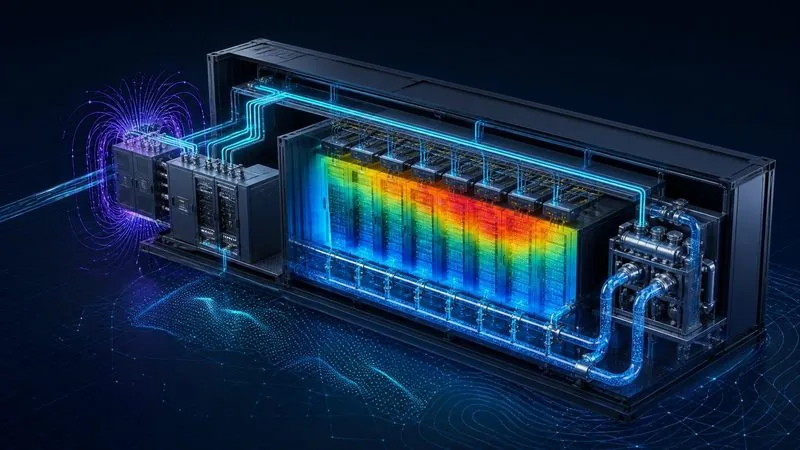
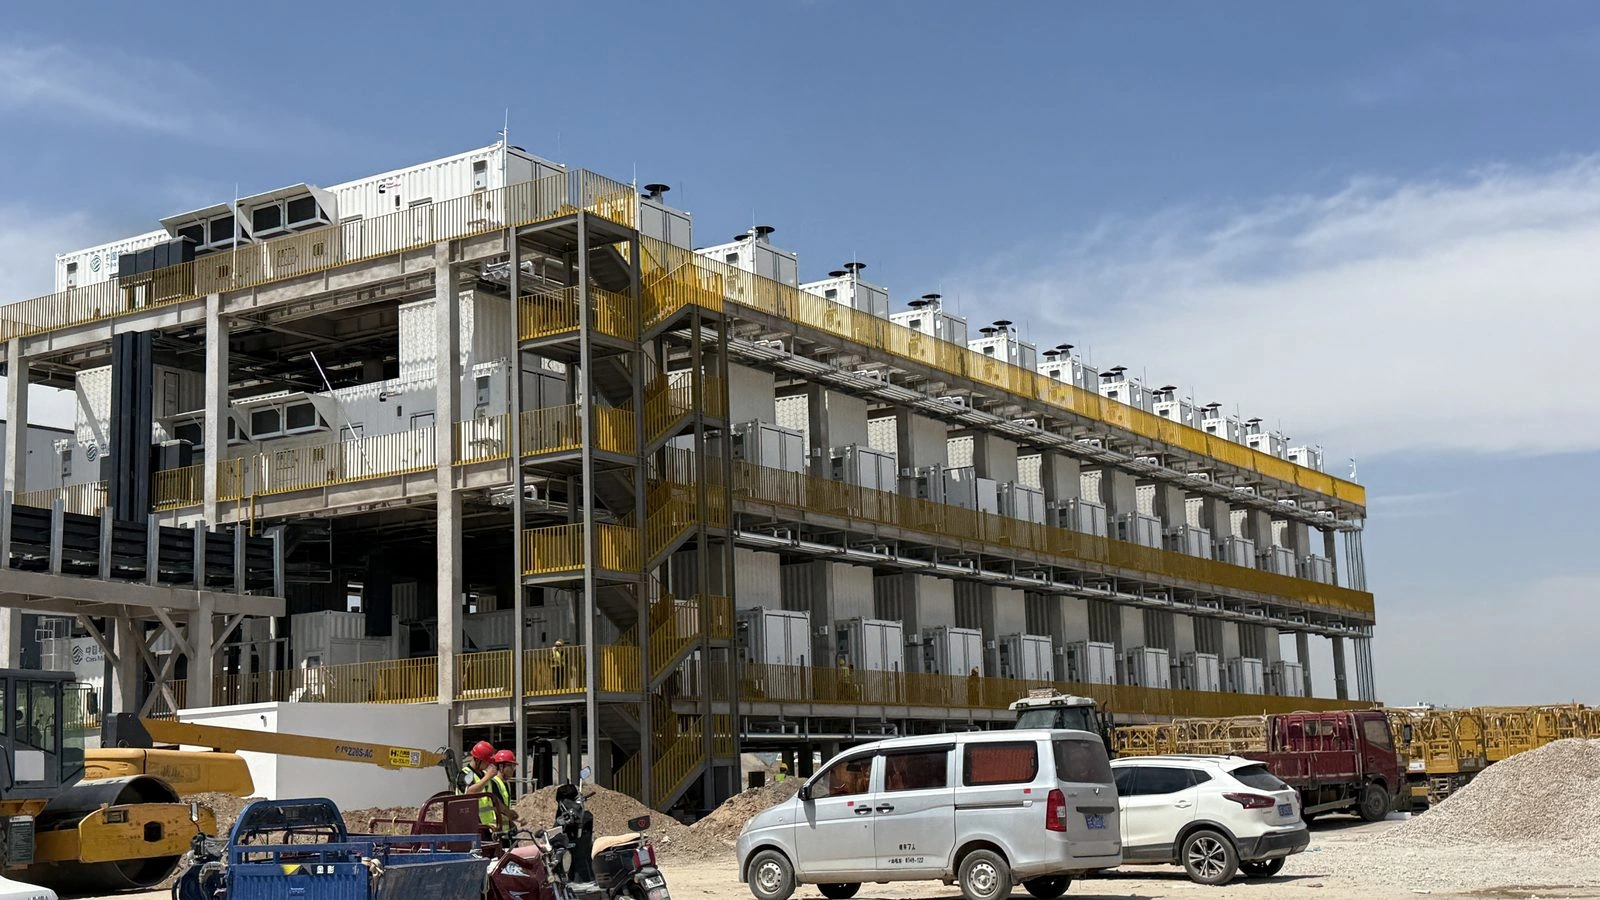
Prefabricated Compute Infrastructure
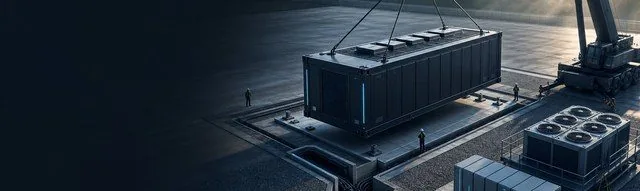
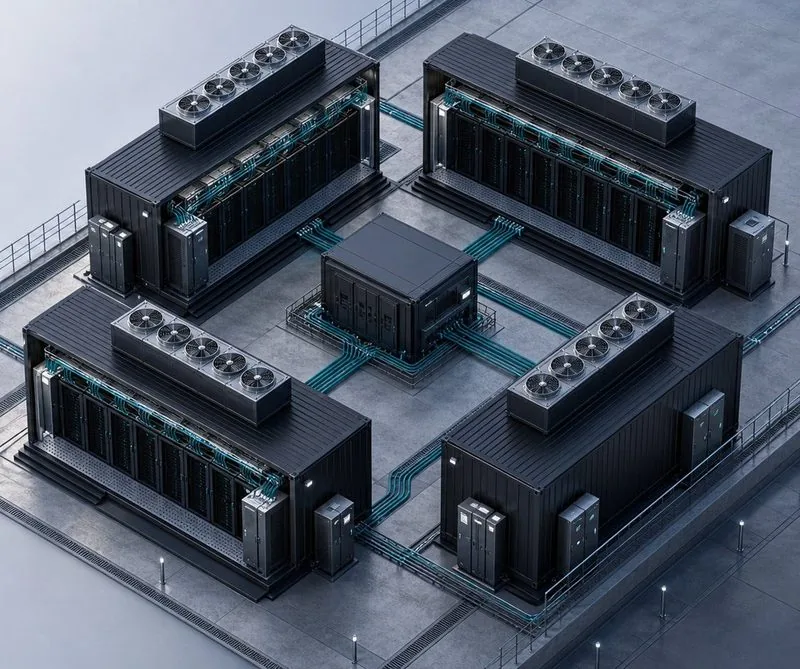
Modular data rooms, prefabricated compute units, and containerized deployment — factory-integrated and rapidly assembled on site to shorten delivery cycles.
Learn more →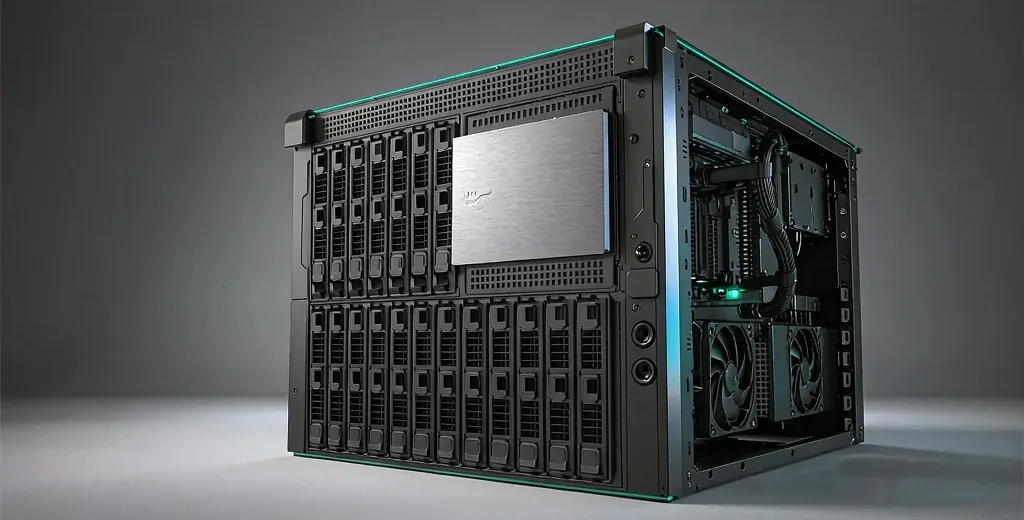
Servers
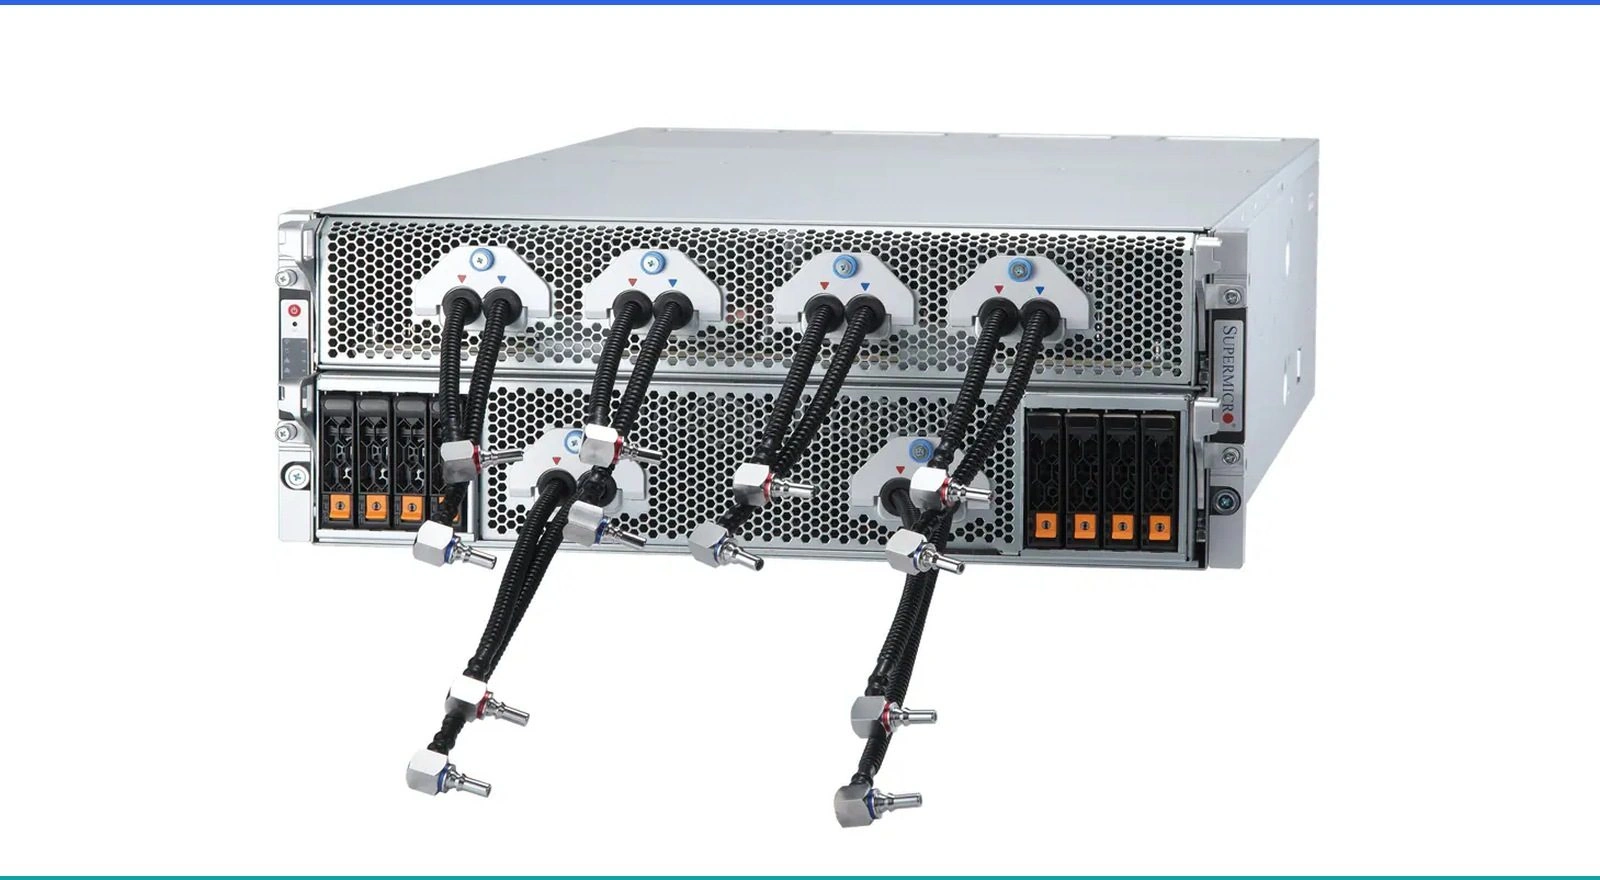
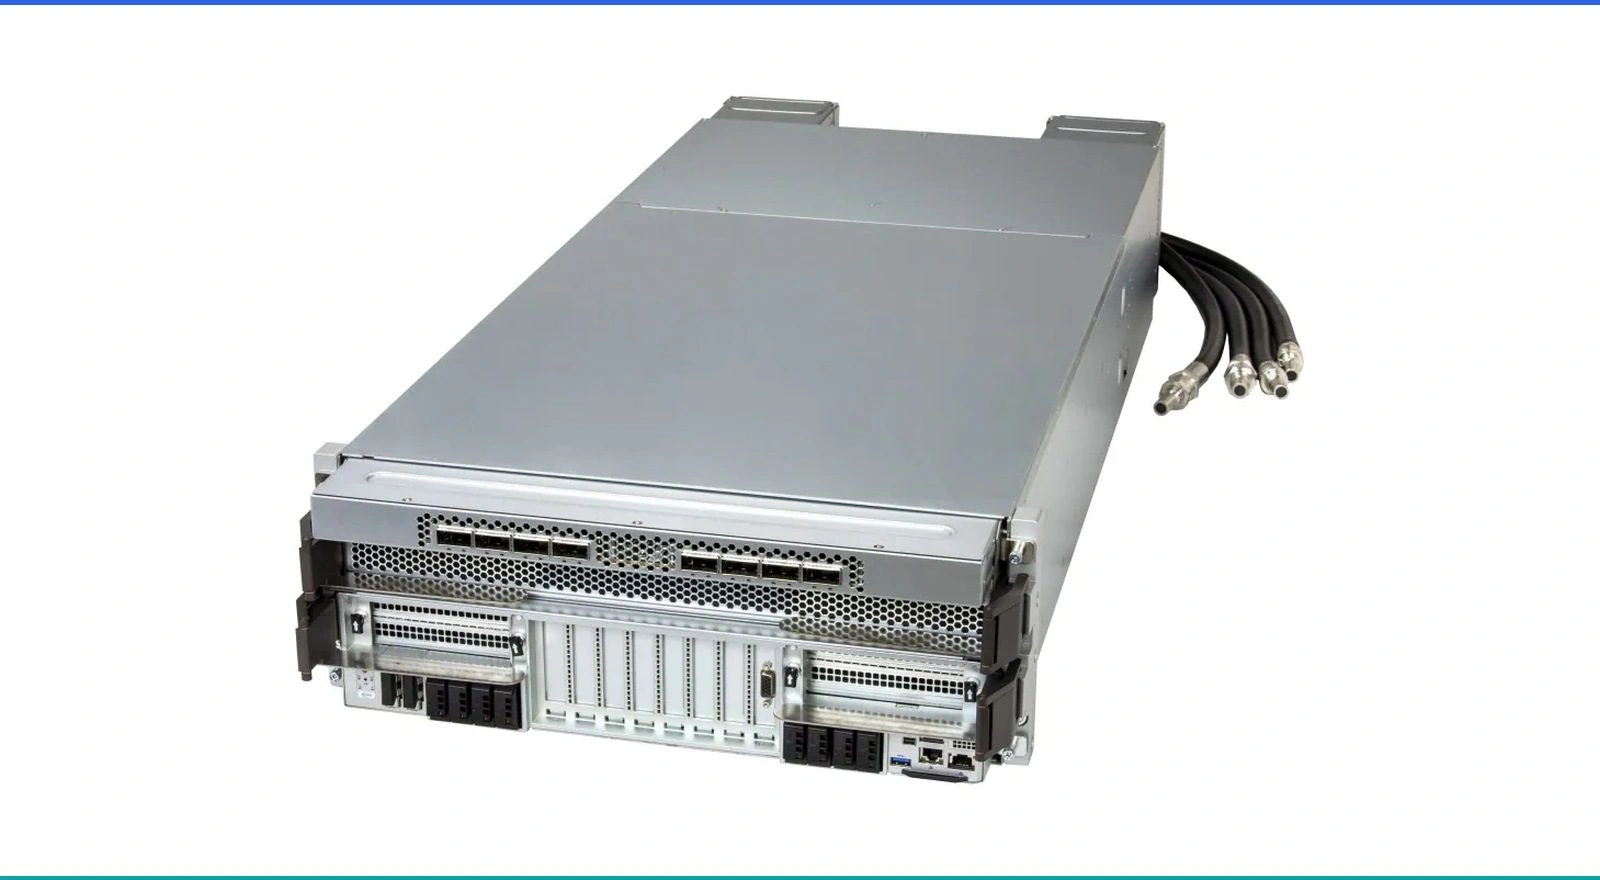
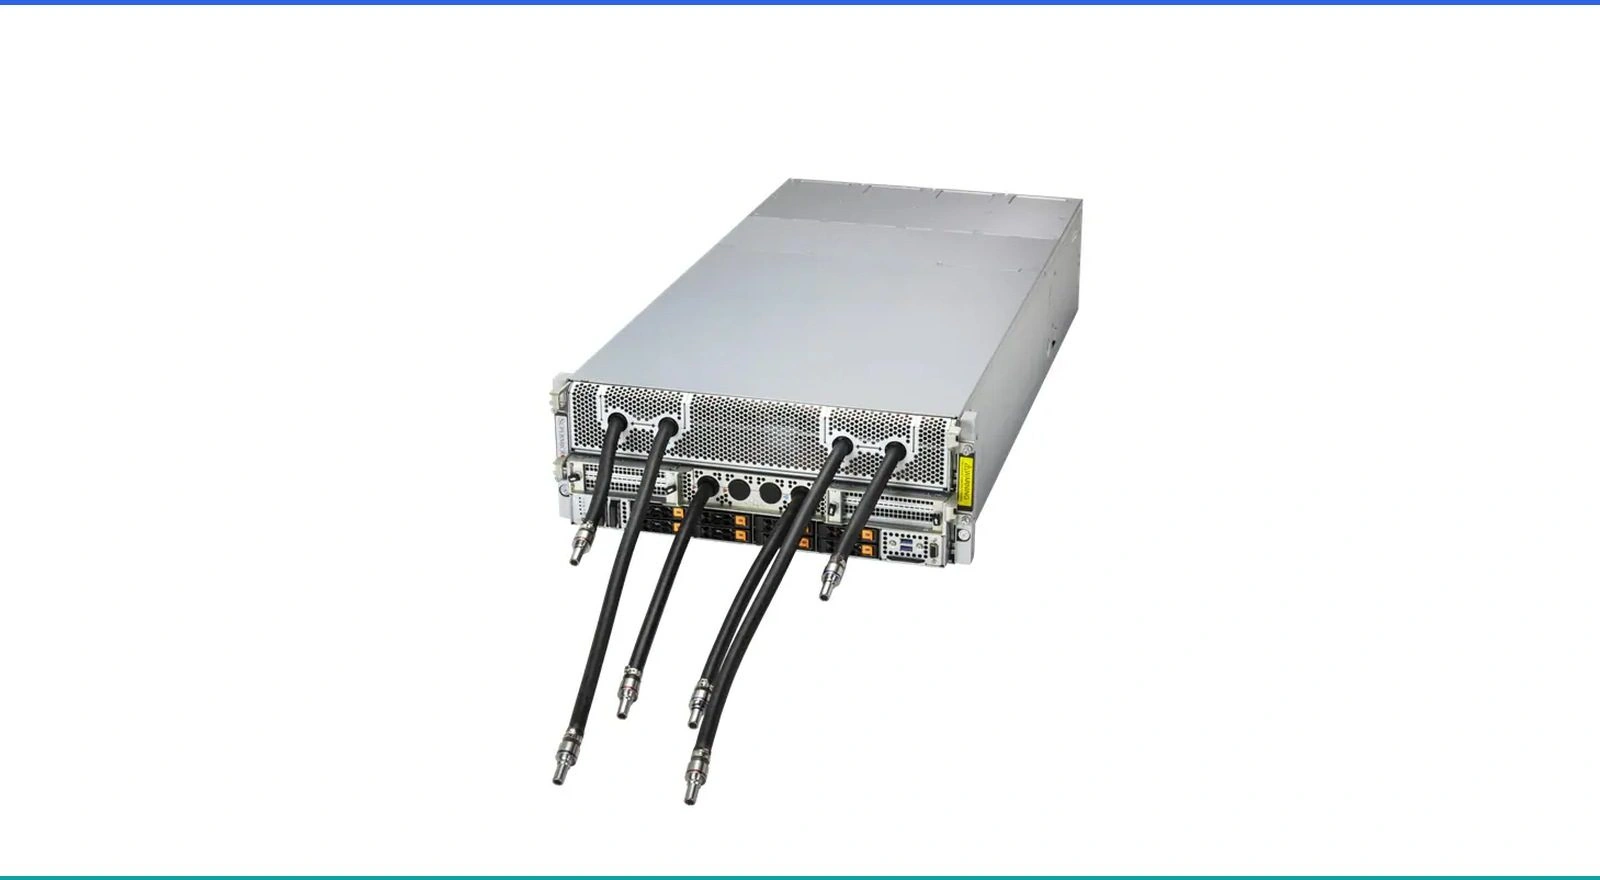
AI GPU server platforms spanning Gen1 through Gen3 — classified by generation, cooling form, CPU/GPU vendor, workload, and GPU interconnect.
Learn more →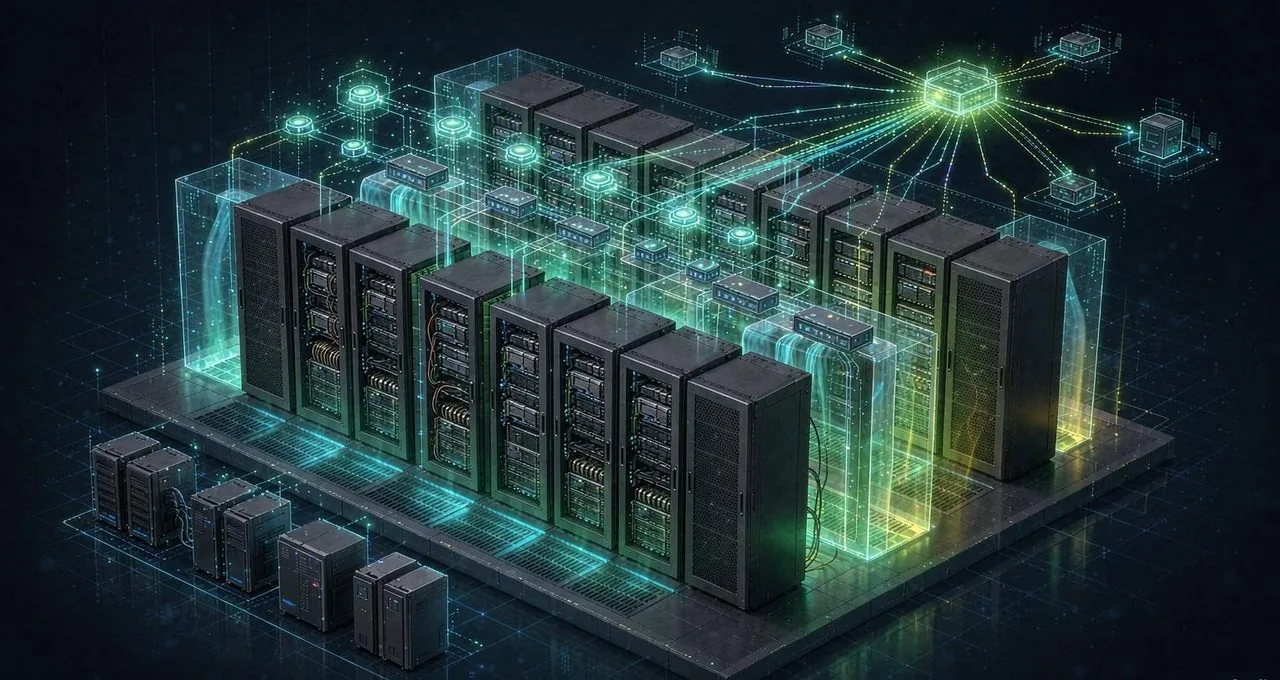
Network & Storage
High-bandwidth, low-latency networking, distributed storage, and parallel file systems deliver the data foundation for large-scale training and inference.
Learn more →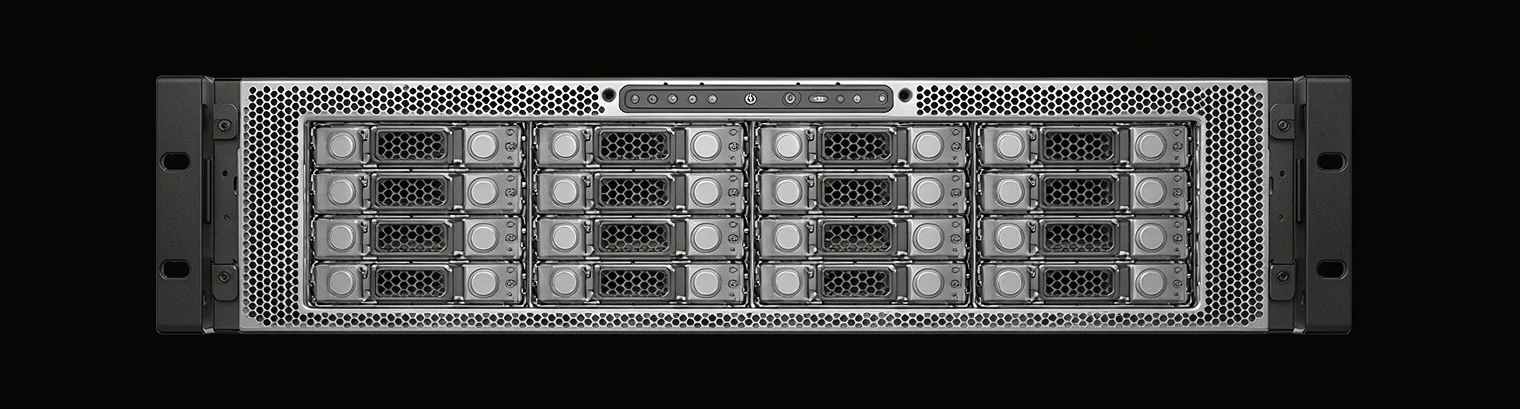
O&M Services
7×24 monitoring, fault early-warning, spare-parts systems, and on-site service keep compute clusters running stably and efficiently.
Learn more →
Compute Token Operations
Compute metering, Token settlement, and revenue sharing turn idle compute into billable, externally available services.
Learn more →Consulting & Solution Design
Consulting · Planning · SimulationGet the math right before you build. Guided by your business goals, we turn ambiguous compute requirements into solutions that are procurable, constructible, and operable — and validate them with a digital twin before breaking ground.
Why front-loaded consulting
AI data centers demand large investment across a long chain; mismatched requirements multiply sunk costs. Starting from model type, concurrency, and data throughput, we derive the right mix of chips, network, storage, and cooling.
We factor in land, power, energy assessment, and compliance constraints to produce a blueprint that balances performance, cost, and scalability.
Requirement Breakdown
Map training/inference workloads, concurrency, and peaks to define compute and bandwidth targets.
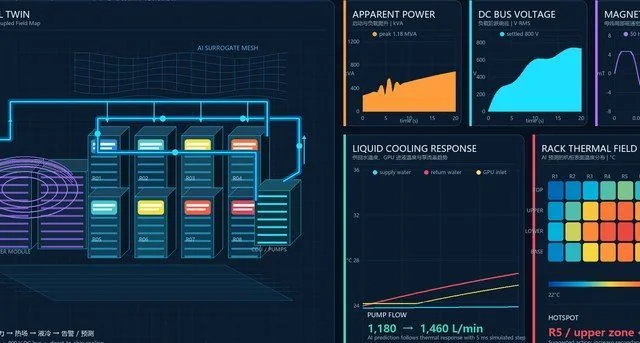
Architecture Design
Integrated design of cluster topology, network tiers, storage architecture, and power & cooling.
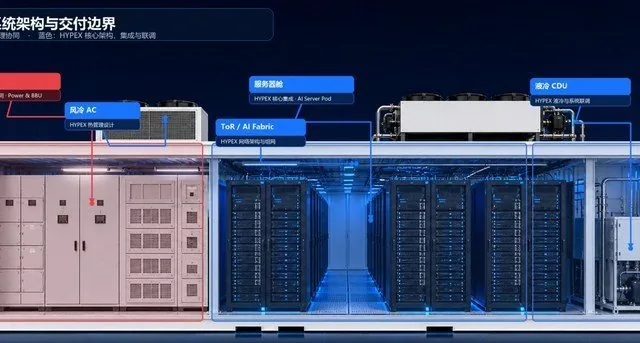
Digital Twin
Validate capacity, energy use, and failure propagation paths in a simulation environment.
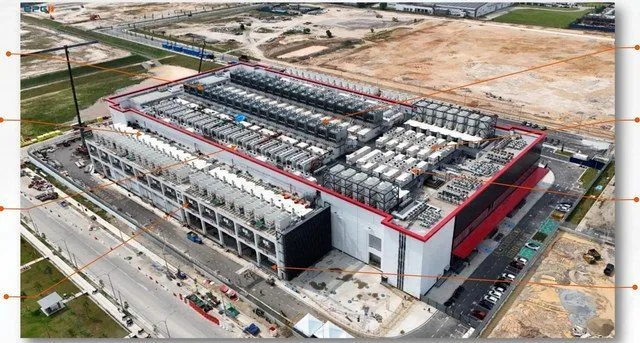
Standards & Compliance
Align with industry standards and data-compliance requirements to reduce delivery risk.
Energy Estimation
Power, cooling, and electrical capacity assessment across load scenarios.
Procurement Advice
Provide key equipment lists and lead times to support procurement decisions.
Cost Estimation
TCO modeling that quantifies total cost of build, O&M, and expansion.
Site Assessment
Comprehensive siting analysis across land, grid, water, and energy-assessment constraints.
Digital Twin: Simulate First, Build Later
Rehearse the real cluster with a virtual mirror, keeping uncertainty on the drawing board.
Capacity Twin
Simulate how node scaling affects bandwidth, storage, and energy at the margins.
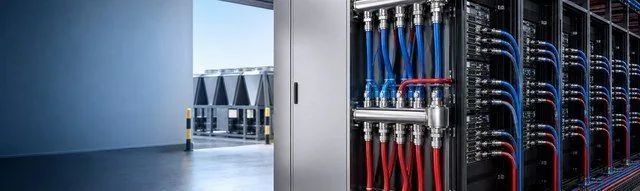
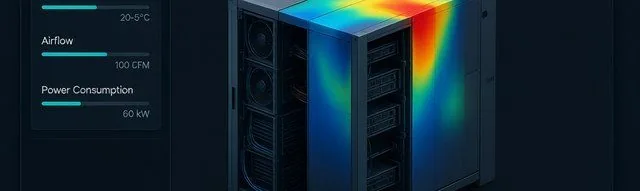
Thermal Twin
Predict rack heat distribution to optimize cooling and airflow design.
Failure Twin
Inject link/node faults to validate redundancy and recovery strategies.
Prefabricated Compute Infrastructure
Factory Integration · Fast DeliveryMove the data room into the factory. Prefabricated modules are integrated, tested, and commissioned in a controlled environment; on site, only assembly and power connection remain — dramatically shortening build time and improving consistency.
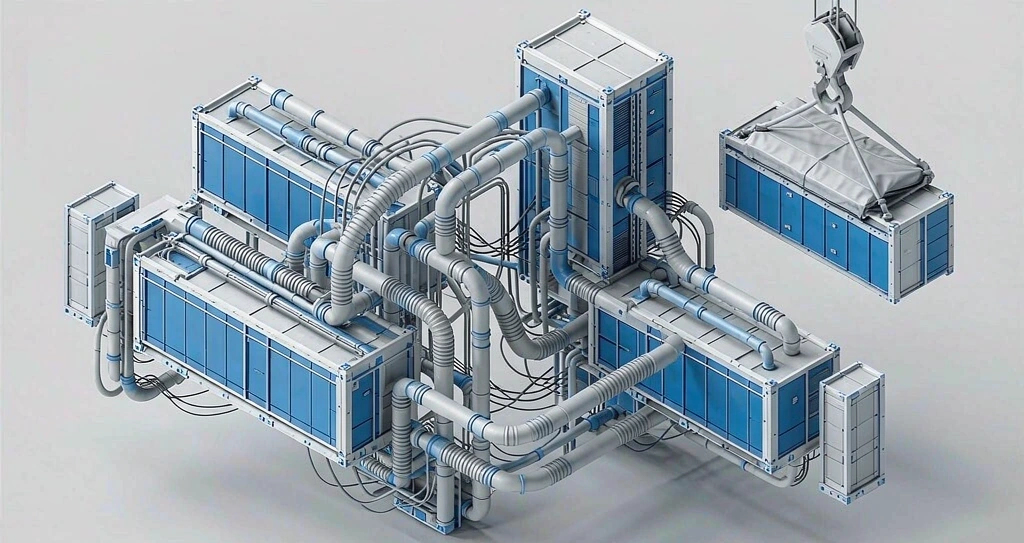
Fewer steps from construction to compute
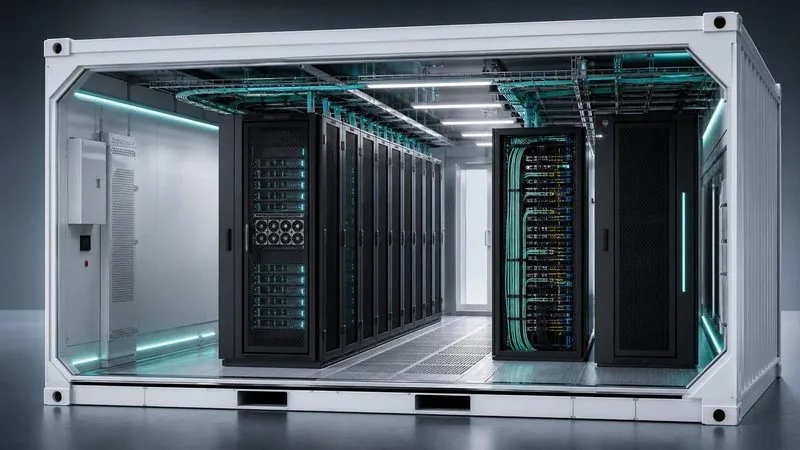
Traditional AI data centers rely on heavy on-site construction where schedule and quality are hard to control. Prefabrication pre-assembles power, cooling, network, and compute into standard modules in the factory, combined on site like building blocks.
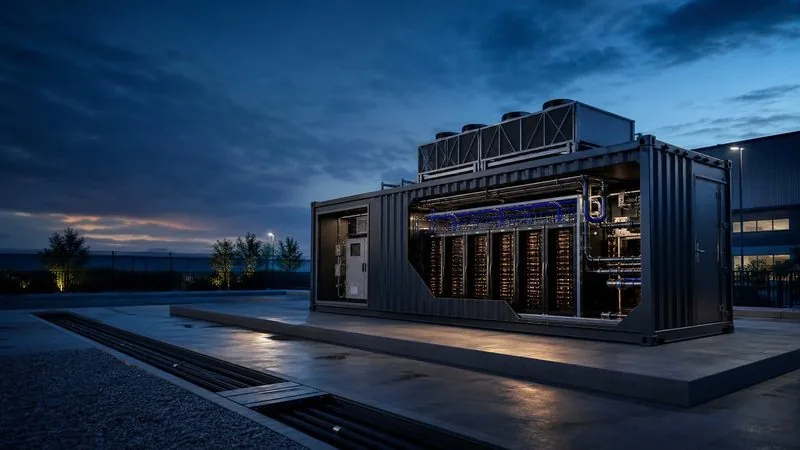
For compute leasing and elastic scaling, containerized units can be deployed in weeks.
Prefabricated Compute Unit
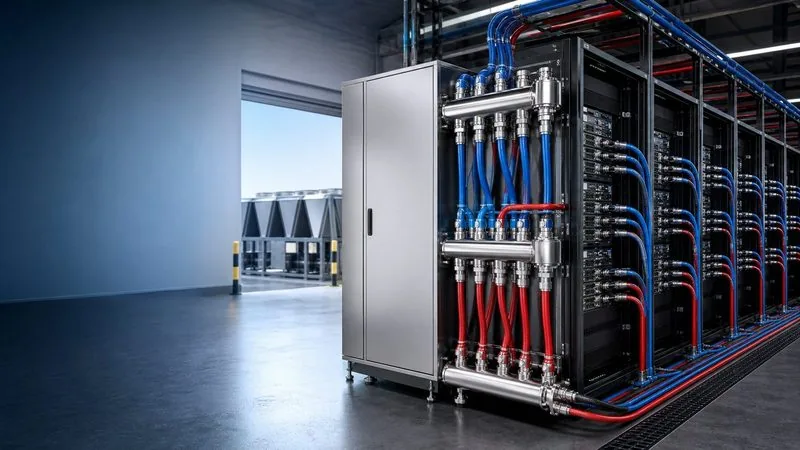
Standard rack unit integrating compute, network, and cooling — plug and play.
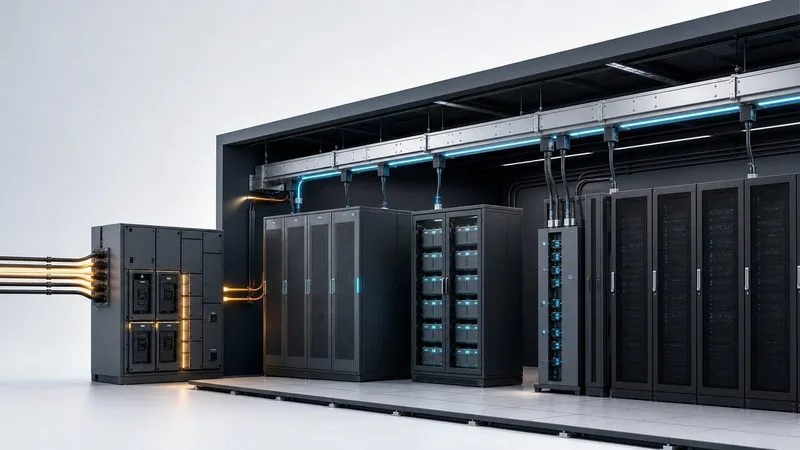
Rapid On-site Assembly
Standard-interface docking shortens on-site construction and commissioning.
Illustrative Delivery Formats
Representative module configurations — for illustration of delivery approach only.
Servers
Gen1–Gen3 · Air / Cold-Plate / ImmersionWe deliver AI GPU server platforms spanning Gen1 through Gen3 — classified by generation, cooling form, CPU/GPU vendor, workload, and GPU interconnect. Tell us your workload and facility, and we size the right platform for you.
Platforms, not SKUs
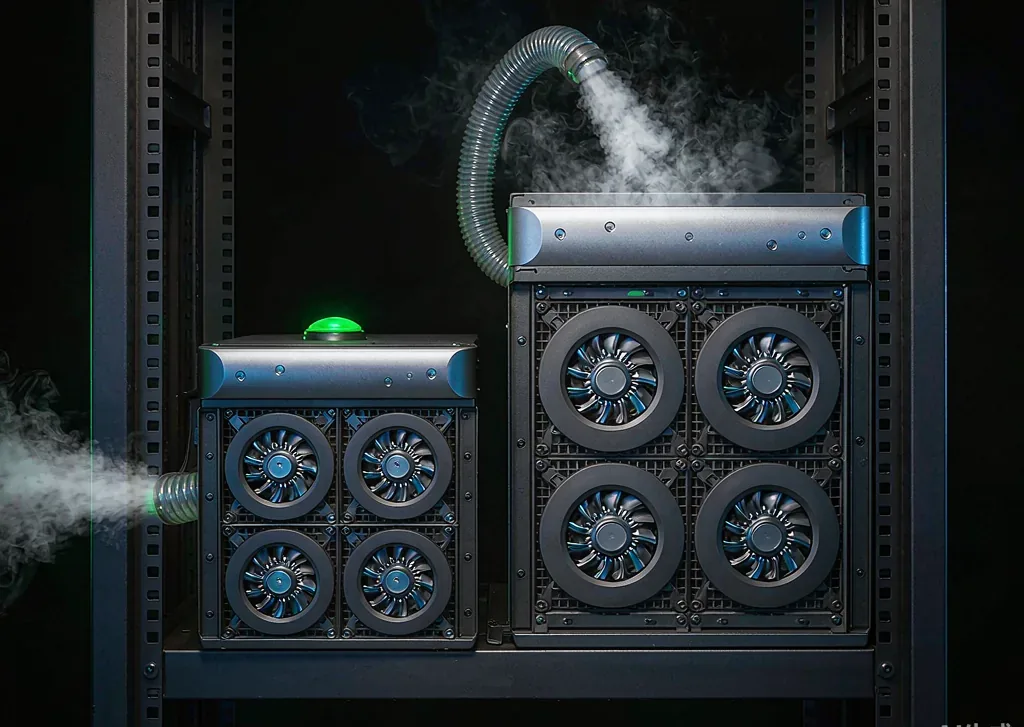
We source and integrate AI GPU server platforms across generations and cooling forms — air, cold-plate liquid, and immersion — and match CPU/GPU vendors and GPU interconnect to your workload and facility.
Only officially released, stable-supply models are listed by platform; unreleased or supply-uncertain parts are marked On request. No OEM white-box brand is named — we keep the focus on chips, platforms, and your needs.
Gen1 · H100/H200 era
GPU NVIDIA H100 / H200 (Hopper). Cooling: Air / Cold-Plate / Immersion. Mainstream large-scale deployment. Contact us for details.
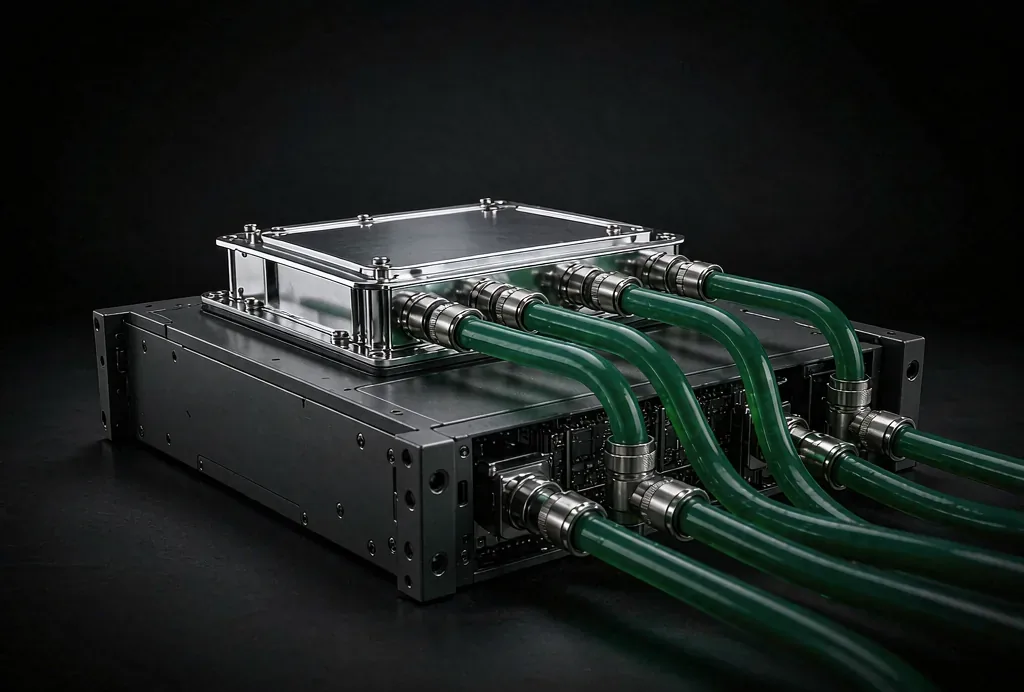
Gen2 · B200 / Blackwell era
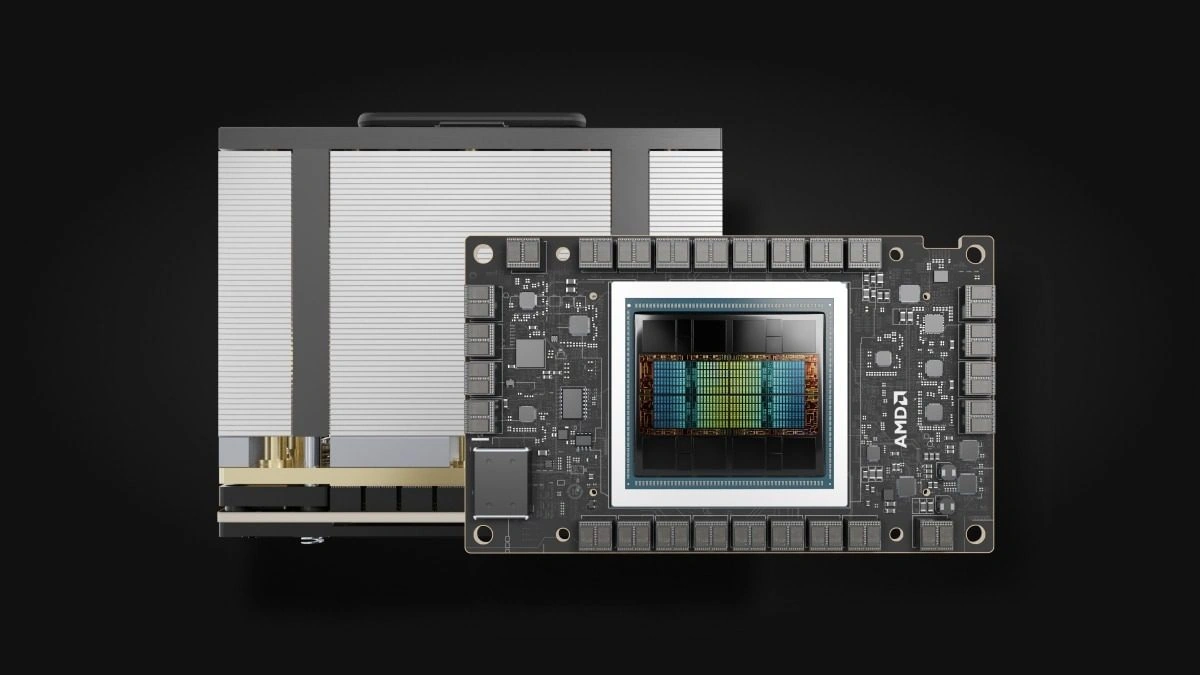
GPU NVIDIA B200 (Blackwell), AMD Instinct MI355X. Cooling: Air / Cold-Plate / Immersion. Generational leap, mainstream. Contact us for details.
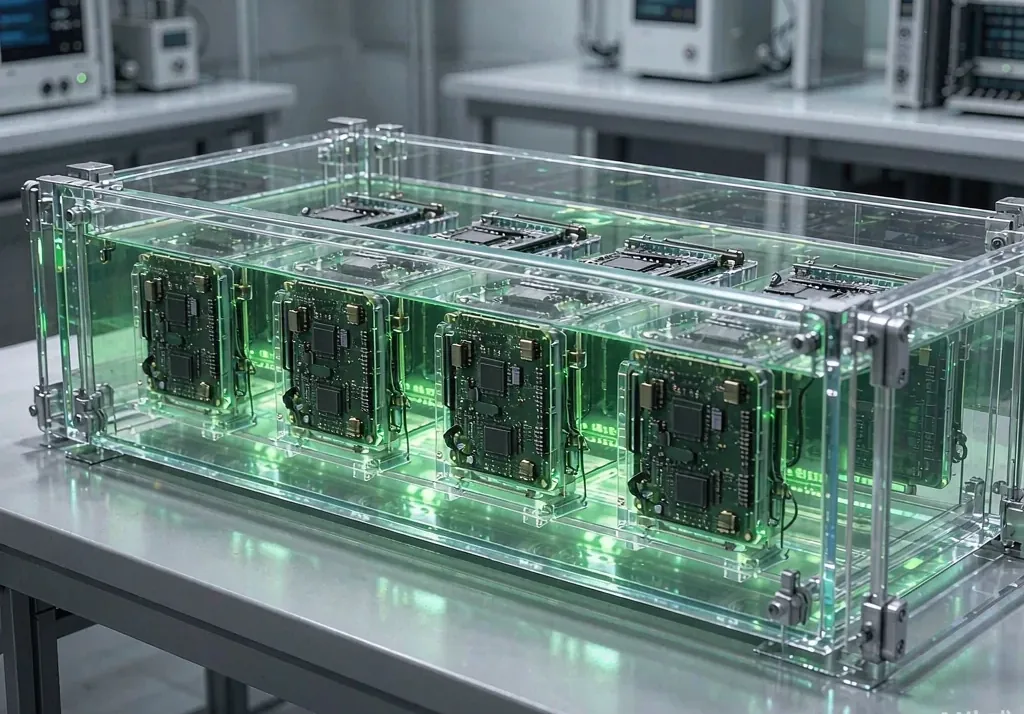
Gen3 · Next-gen Platforms
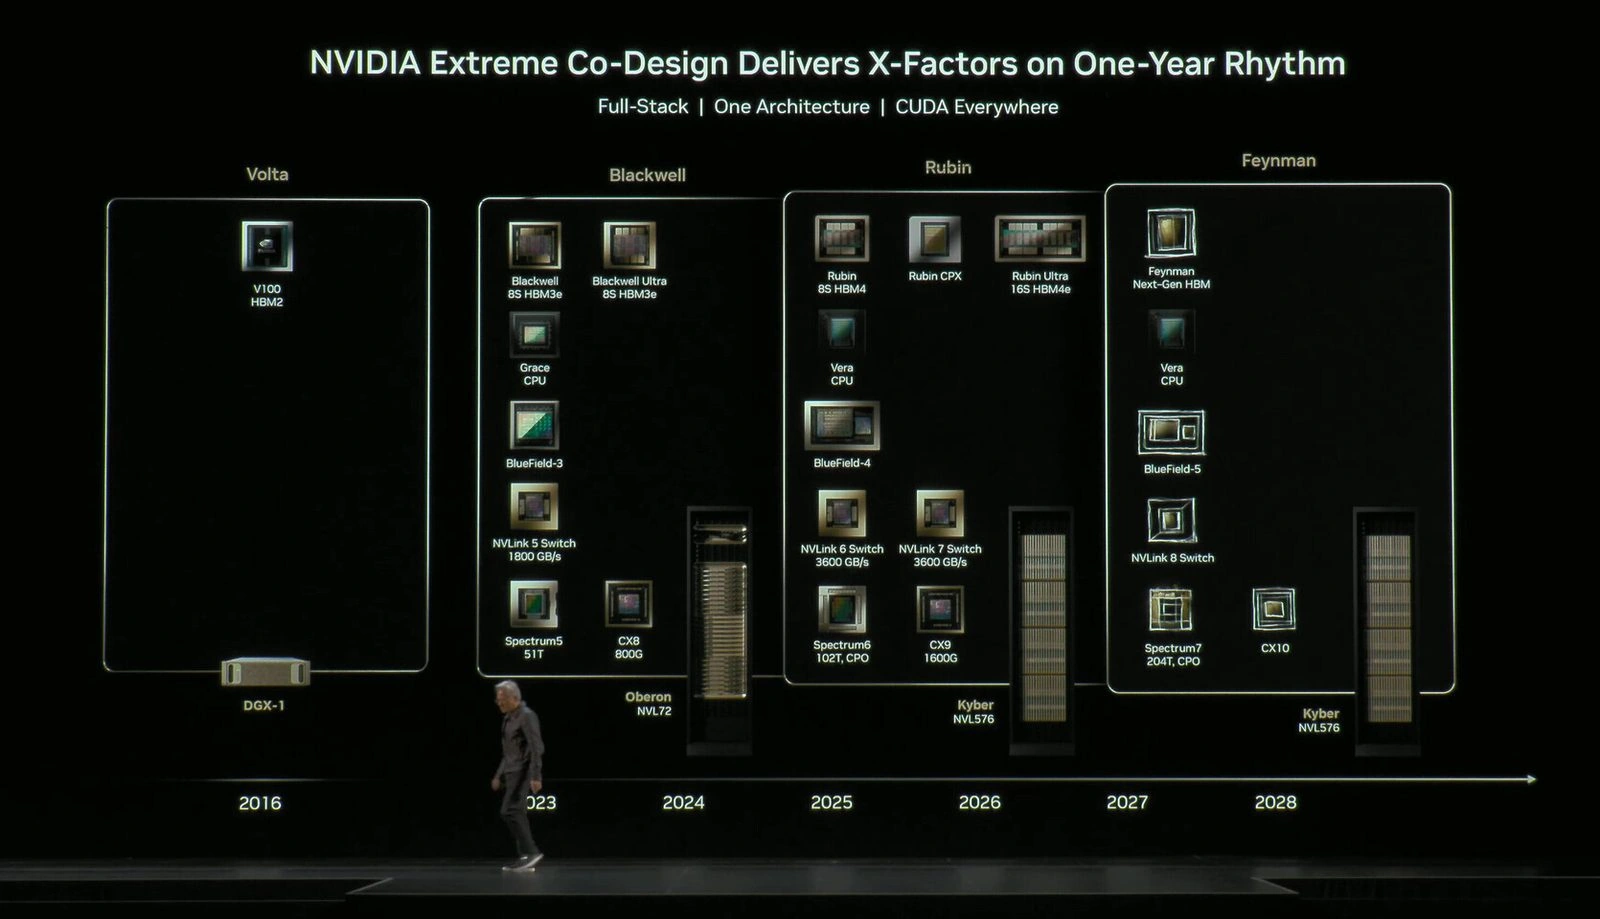
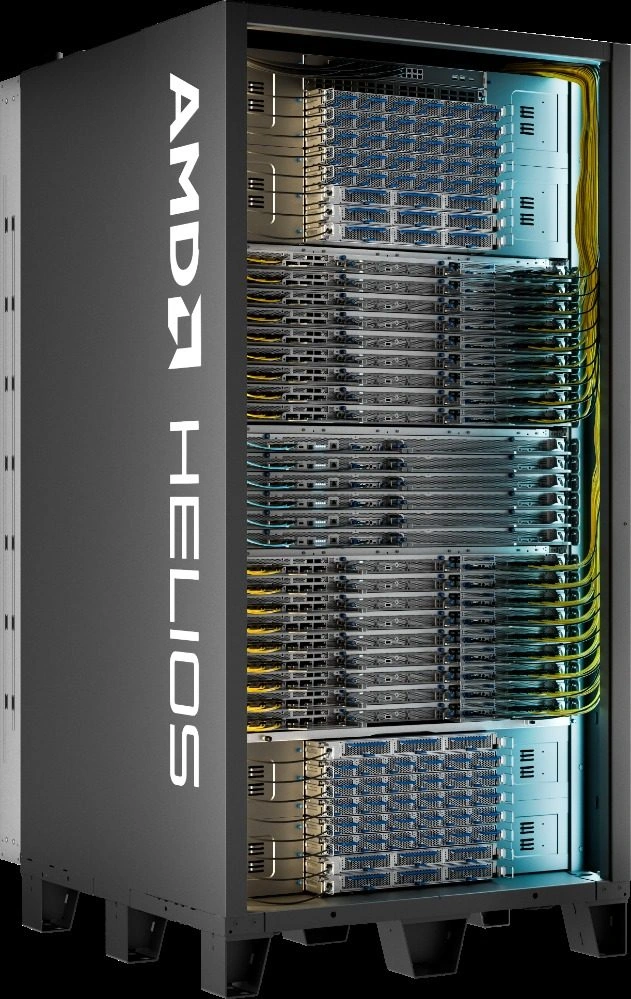
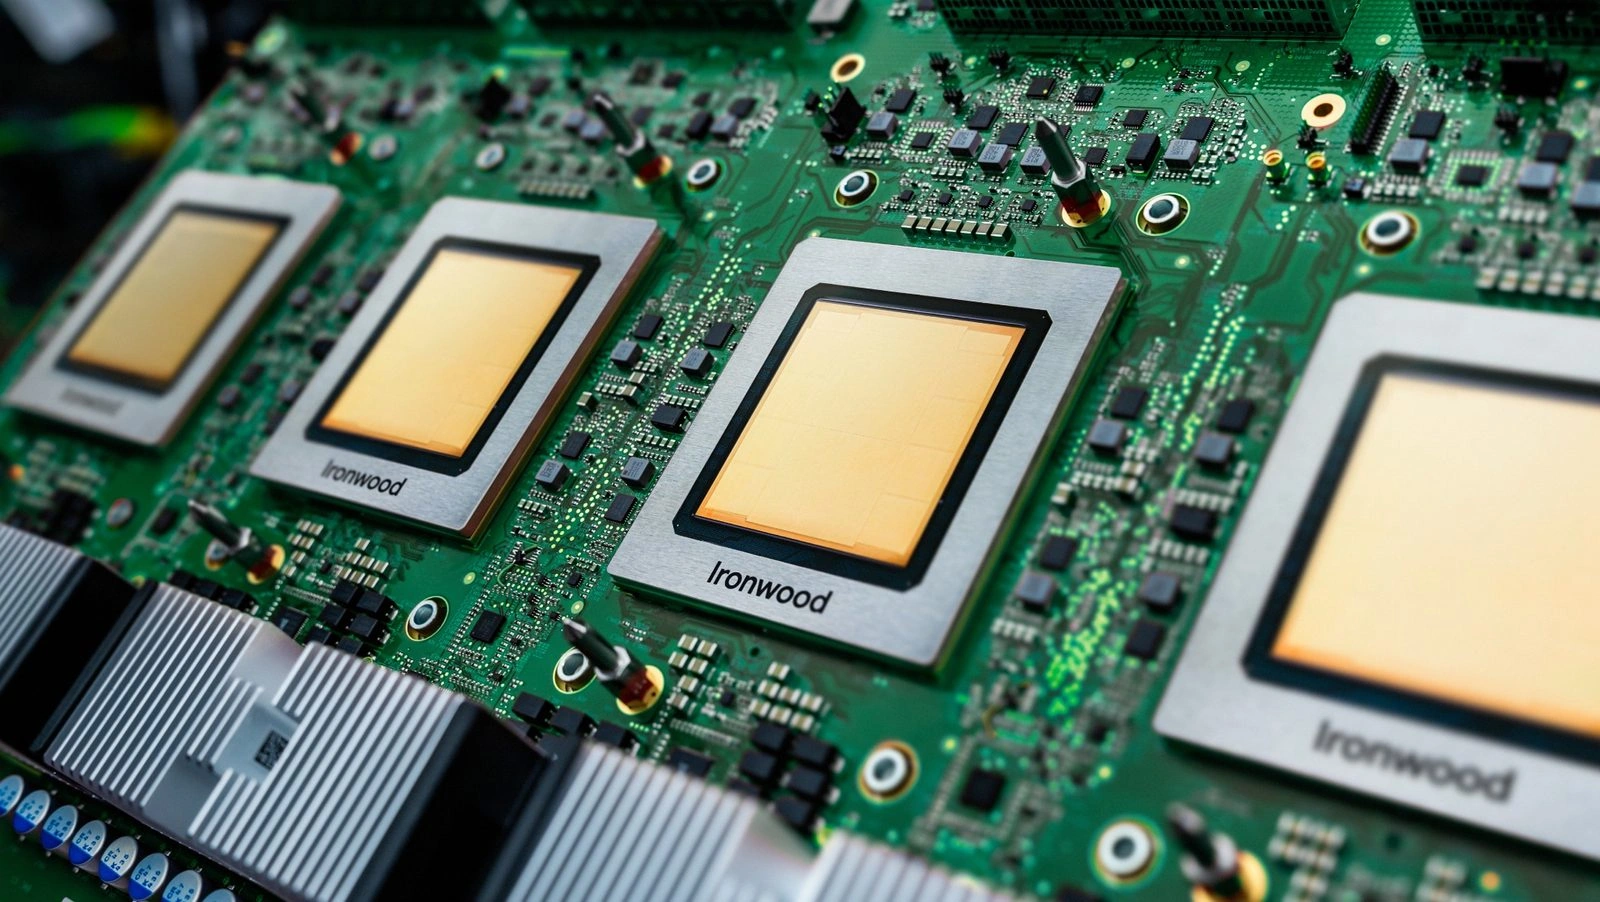
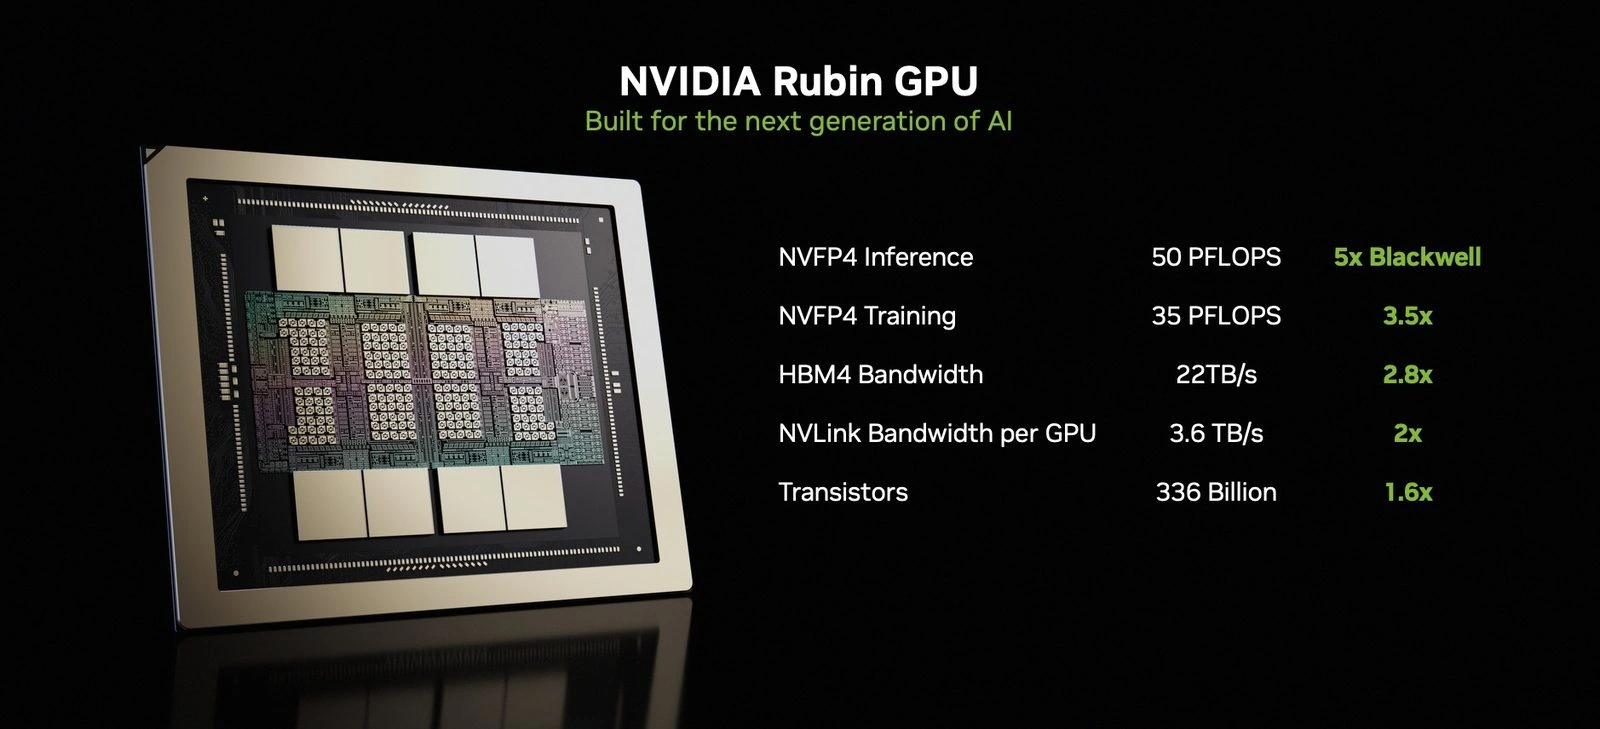
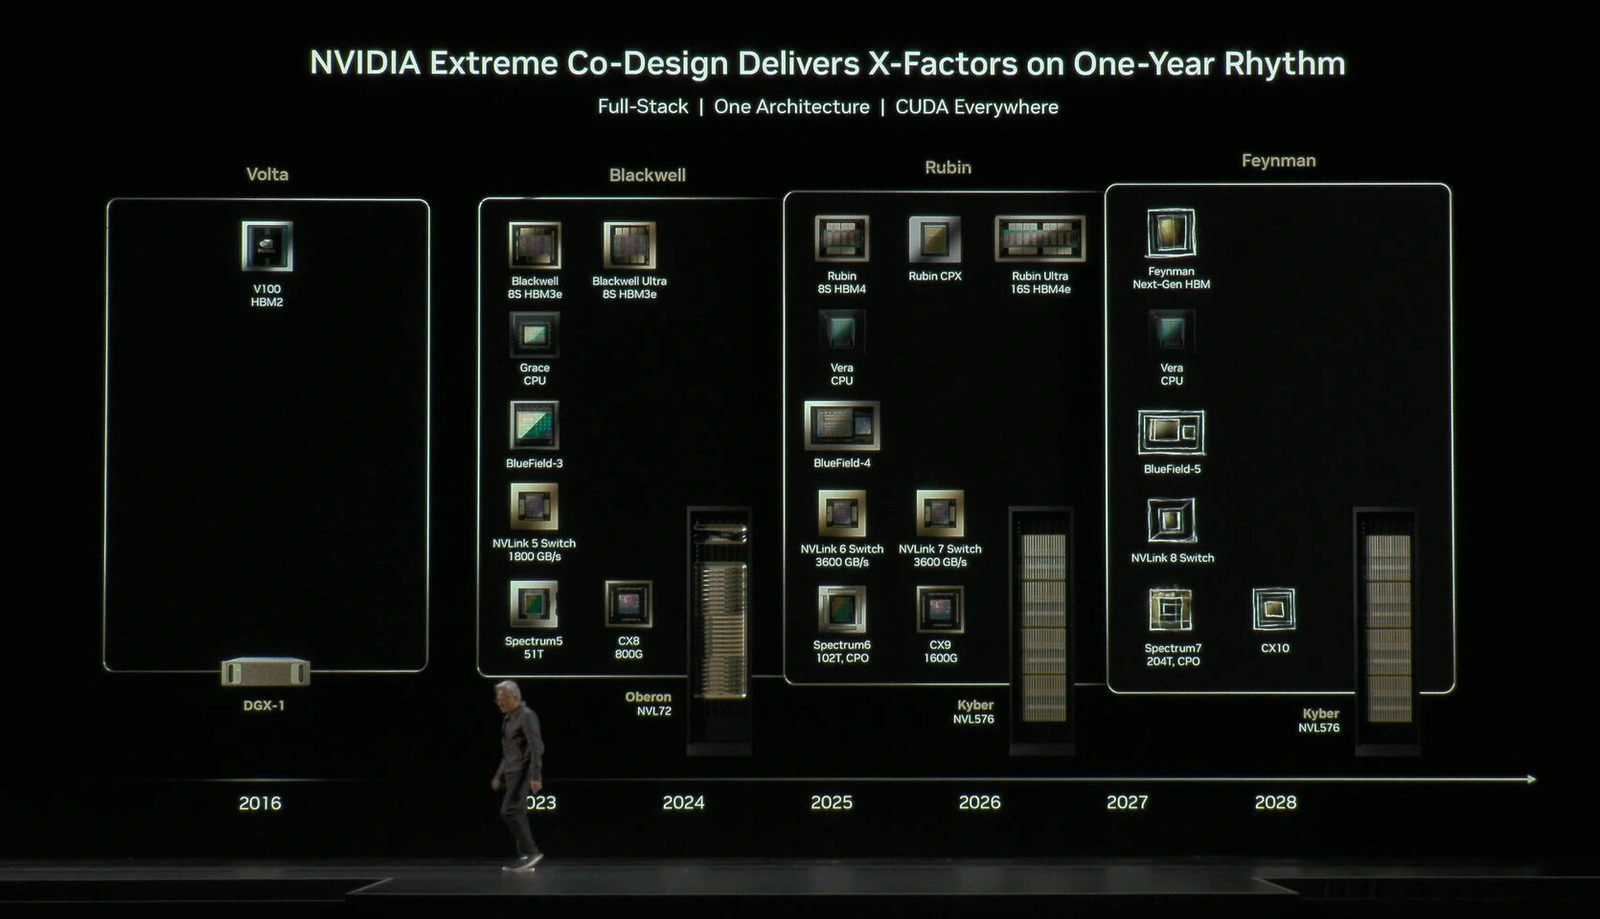
GPU NVIDIA next-gen platforms, AMD next-gen Instinct, China-produced accelerators (on request). Cooling: Cold-Plate / Immersion. Forward-looking roadmap. Contact us for details.
Classification Logic
Six dimensions define every platform we deliver.
| Dimension | Values (platform-level, public) |
|---|---|
| Generation | Gen1 (H100/H200, released) · Gen2 (B200 etc Blackwell, released / on request) · Gen3 (next-gen platforms, 2026–27 Roadmap, on request) |
| Cooling | Air · Cold-Plate · Immersion |
| CPU Vendor | INTEL Xeon (Xeon 6/8/9) · AMD EPYC (9005 Turin/Venice/Florence) |
| GPU Vendor | NVIDIA (Hopper / Blackwell, released only) · AMD Instinct (MI355X etc released) · China-produced accelerators (on request) |
| Workload | Compute · AI Train · AI Infer · Agent |
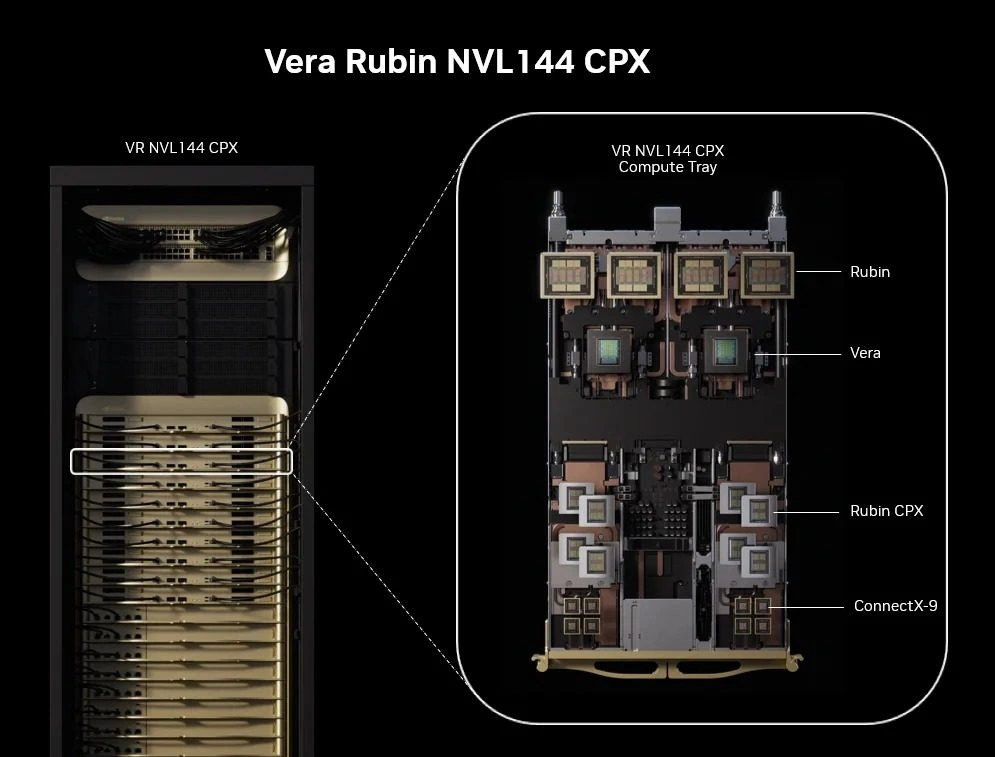
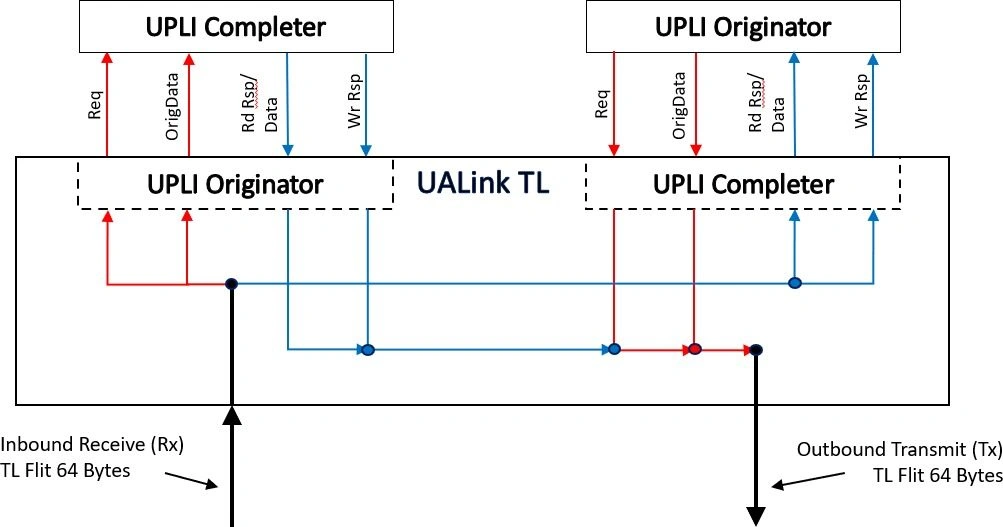
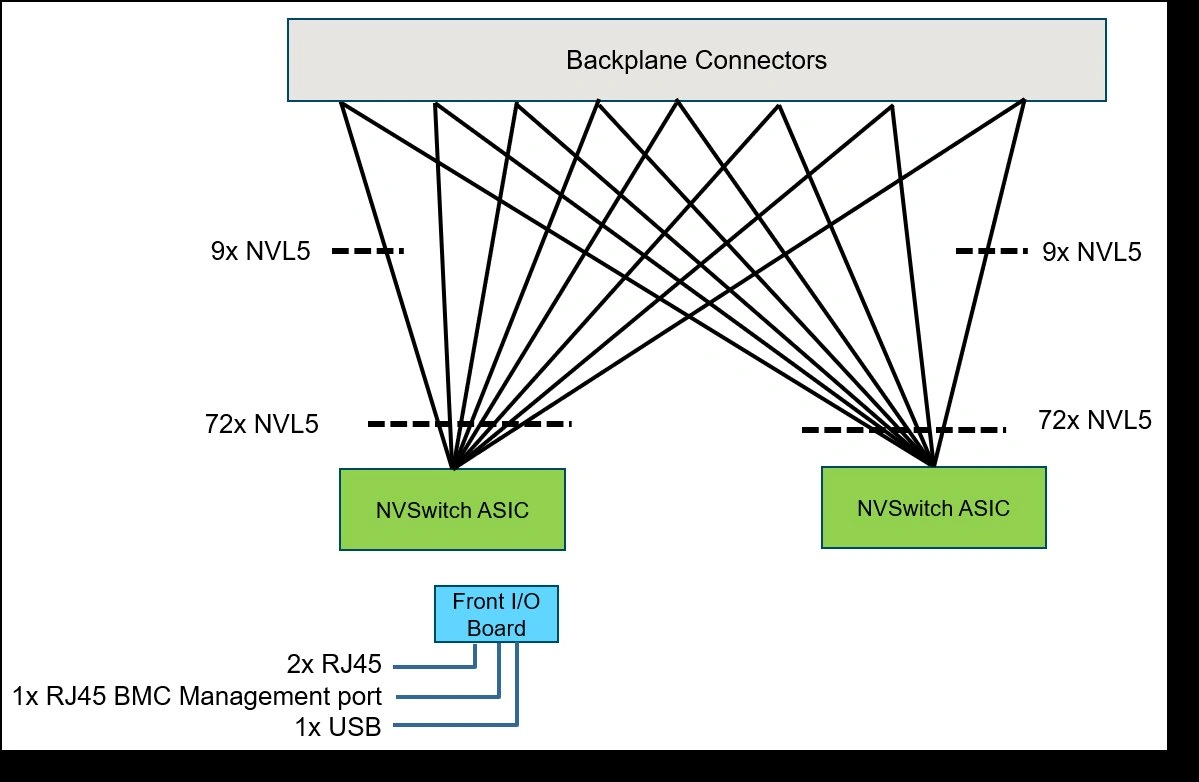
| GPU Interconnect | NVLink · NVSwitch · NVL144 / NVL576 · UALink (open standard) · ICI (TPU-class) · NVLink over Fabrics |
Generation Comparison
No hard commitments — supply status reflects public availability only.
| Generation | GPU Platform | CPU | Cooling | Workload | GPU Interconnect | Supply |
|---|---|---|---|---|---|---|
| Gen1 · H100/H200 | NVIDIA H100 / H200 (Hopper) | INTEL Xeon / AMD EPYC | Air · Cold-Plate · Immersion | Compute · Train · Infer | NVLink (Hopper) | Available |
| Gen2 · Blackwell | NVIDIA B200 (Blackwell); AMD Instinct MI355X | INTEL Xeon 6 (Granite Rapids) · AMD EPYC 9005 (Turin/Venice) | Air · Cold-Plate · Immersion | Train · Infer · Agent | NVLink Domain / NVSwitch | Available / On request |
| Gen3 · Roadmap | NVIDIA next-gen platforms · AMD next-gen Instinct · China-produced accelerators | INTEL Xeon 8/9 · AMD EPYC Venice/Florence | Cold-Plate · Immersion | Train · Infer · Agent | NVL144/NVL576 · UALink · ICI · NVLink over Fabrics | Roadmap 2026–27 |
Unreleased or supply-uncertain models are intentionally not listed by part number. China-produced accelerators are summarized at the platform level (on request). OEM white-box brands (Dell / Supermicro / Lenovo / ASUS / Quanta / Inspur / Wiwynn) do not appear on this site.
Workload Positioning
Match the generation to the job.
General Compute
Gen1 / Gen2, air-cooled — cost-efficient for inference and mixed workloads.
Large-model Training
Gen2 / Gen3, liquid-cooled — scale-up interconnect for massive clusters.
AI Inference
Gen1 / Gen2 / Gen3 — flexible deployment across cooling forms.
Agent AI
Gen3 — interconnect-rich platforms for agentic and reasoning workloads.
Contact us for details
Inquiry-based — we do not publish SKUs or prices. Tell us your workload and facility.
Network & Storage
High Bandwidth · Low LatencyThe bottleneck is rarely the chip — it's data movement. With high-bandwidth networking and parallel storage, we keep GPUs continuously "fed".
A data foundation built for large-scale training
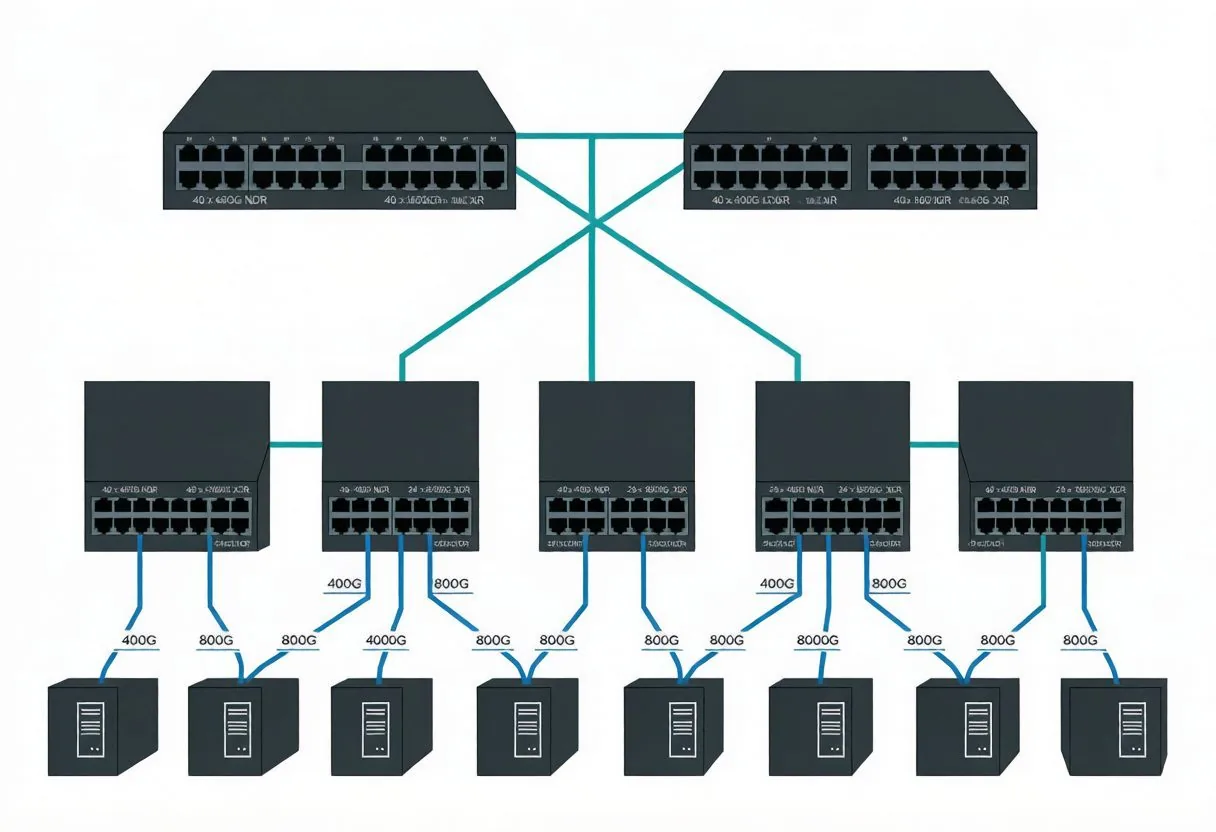
Training clusters demand extremely high network throughput and storage concurrency. We provide tiered networks, RDMA high-speed interconnects, and distributed parallel file systems to cut wait times and raise effective compute utilization.
Storage is tiered for checkpoints, datasets, and vector stores — balancing capacity, bandwidth, and cost.
High-Speed Networking
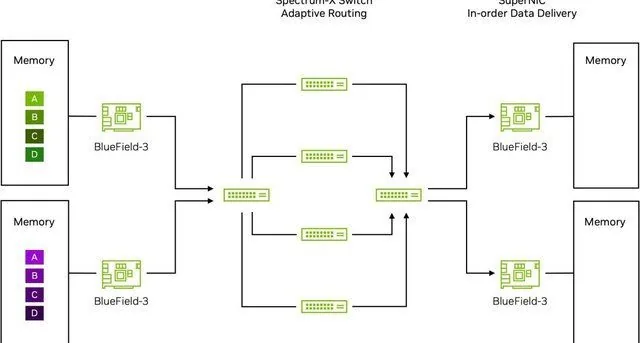
Low-latency, non-blocking topology that supports multi-node, multi-card collective communication.
Parallel File System
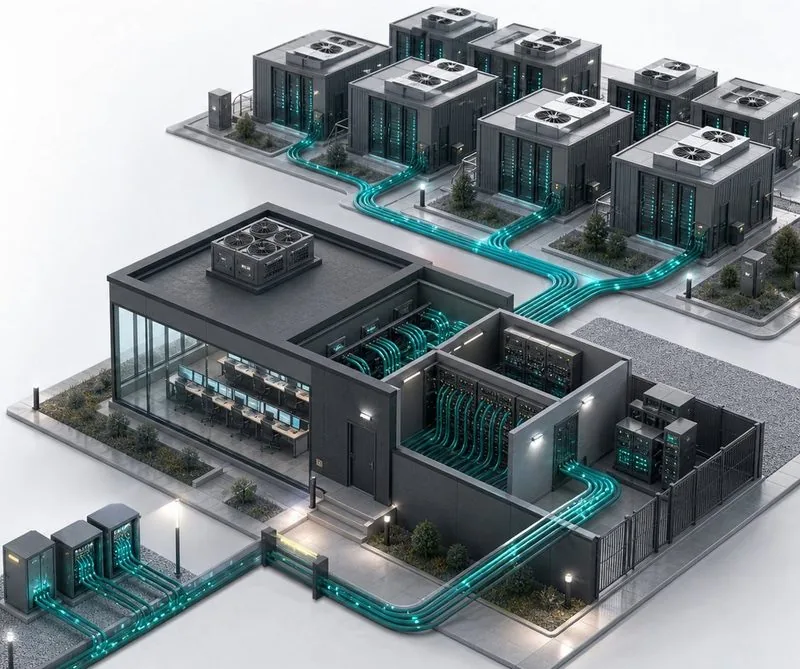
Horizontally scalable storage for high-concurrency training data reads.
Tiered Storage
Hot/warm/cold tiers balance performance with total cost of ownership.
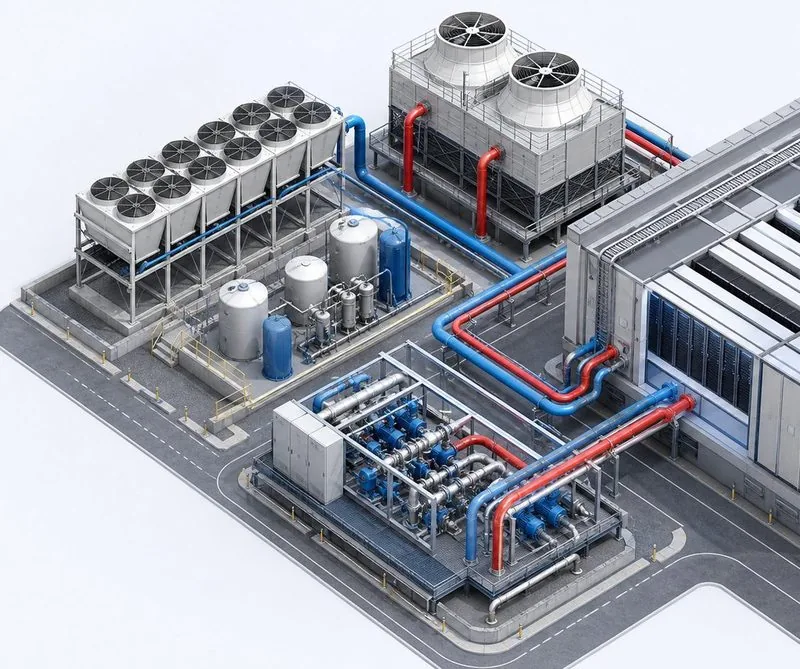
Data Mobility
Unified namespace and data orchestration for efficient cross-cluster flow.
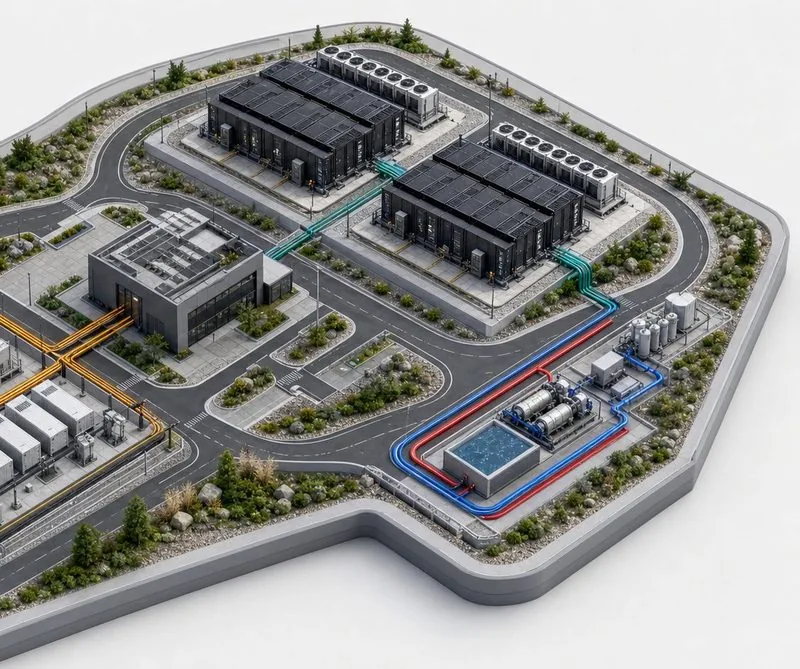
Reliability
Multi-replica and erasure coding protect training assets from loss.
Observability
Traffic and throughput monitoring to quickly locate congestion and bottlenecks.
O&M Services
Stable · Efficient · PredictableBuilding the compute is only the beginning. Our standardized O&M system and localized service keep clusters stable and highly available over the long run.
Keep compute always online
From monitoring alerts to incident response, we build a full-stack O&M view spanning devices, links, and services, using automation to reduce human error and spare parts to shorten recovery time.
On-site and remote coordination, with resident engineers and periodic inspections for critical scenarios.
7×24 Monitoring
Full-stack metric collection and alerting with second-level anomaly detection.
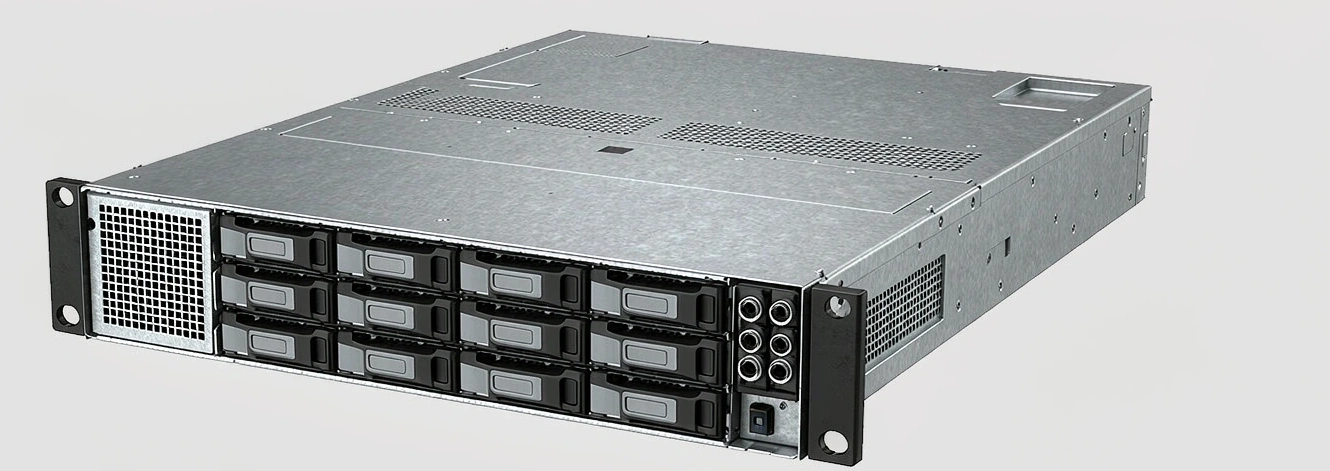
Fault Early-Warning
Trend-based early warning turns reactive into proactive.
Spare Parts System
Pre-positioned inventory of critical parts shortens replacement cycles.
On-site Service
Localized engineering teams for rapid response.
Performance Tuning
Continuously unlock effective compute utilization across the cluster.
Change Management
Standardized processes reduce upgrade and scaling risks.
Security & Compliance
Access control and auditing protect compute and data.
Operations Reports
Visualize usage, availability, and cost.
Compute Token Operations
Metered AI compute — pay for what you useTurn compute into a measurable, billable, operable service. HYPEX AI provides Compute Token operations spanning metering, billing, and revenue sharing — moving the AI data center from asset to revenue.
From "owning compute" to "operating compute"
After build, the key question is utilization and return. Using Token as a unified unit of measure, we precisely bill training, inference, and leasing, and support external operations with revenue sharing.
Operations dashboards show throughput, unit price, and revenue in real time, making every unit of compute visible and priced.
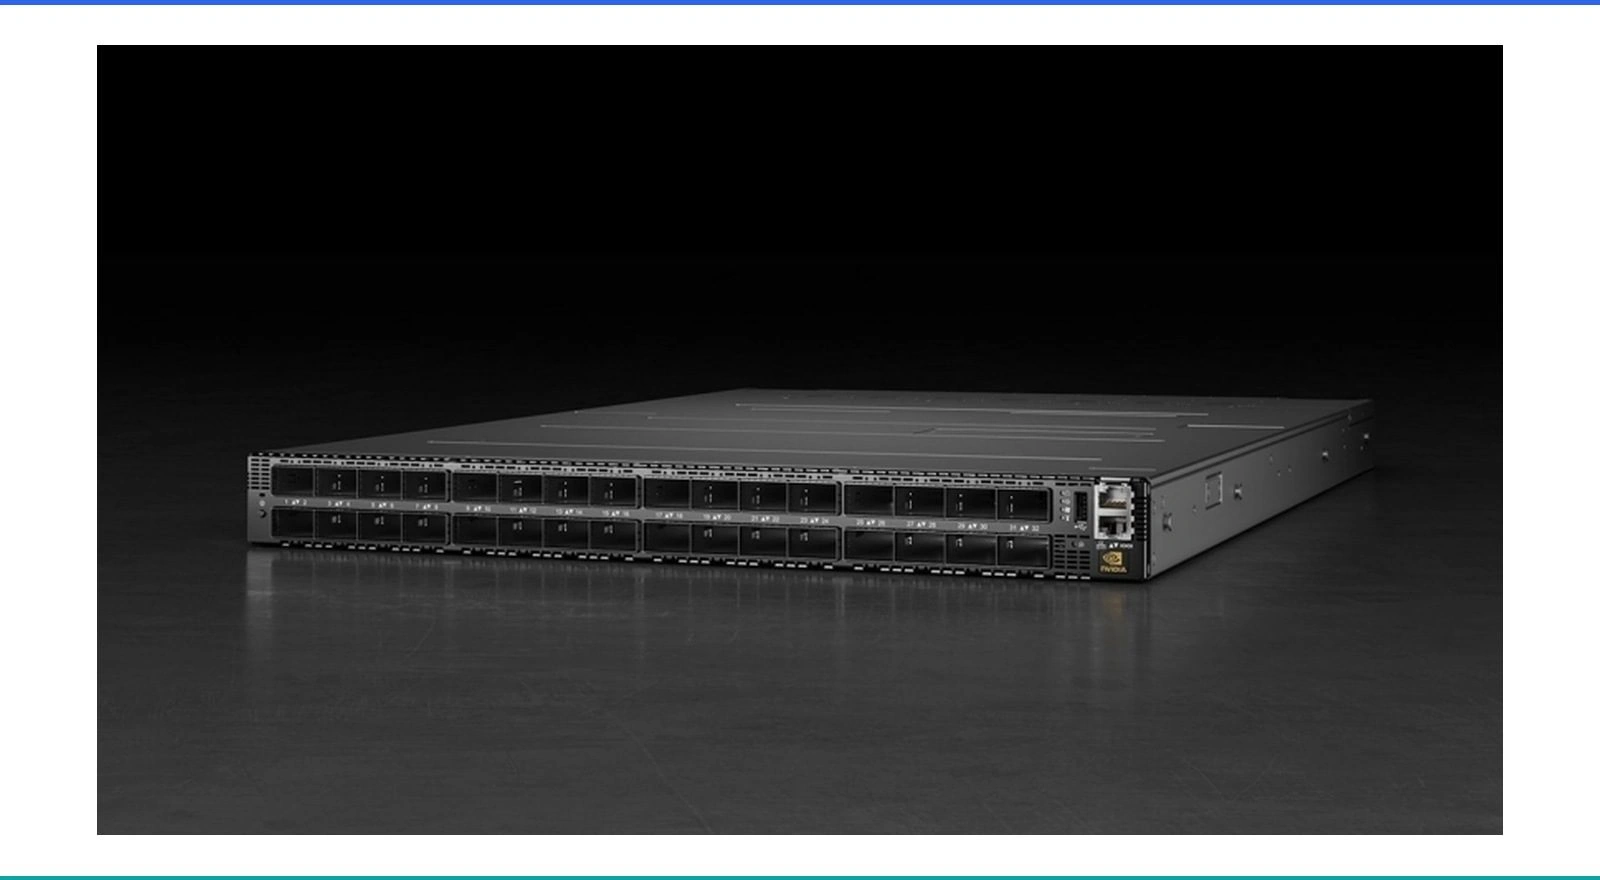
Unified Metering
Token normalizes compute consumption across different workloads.
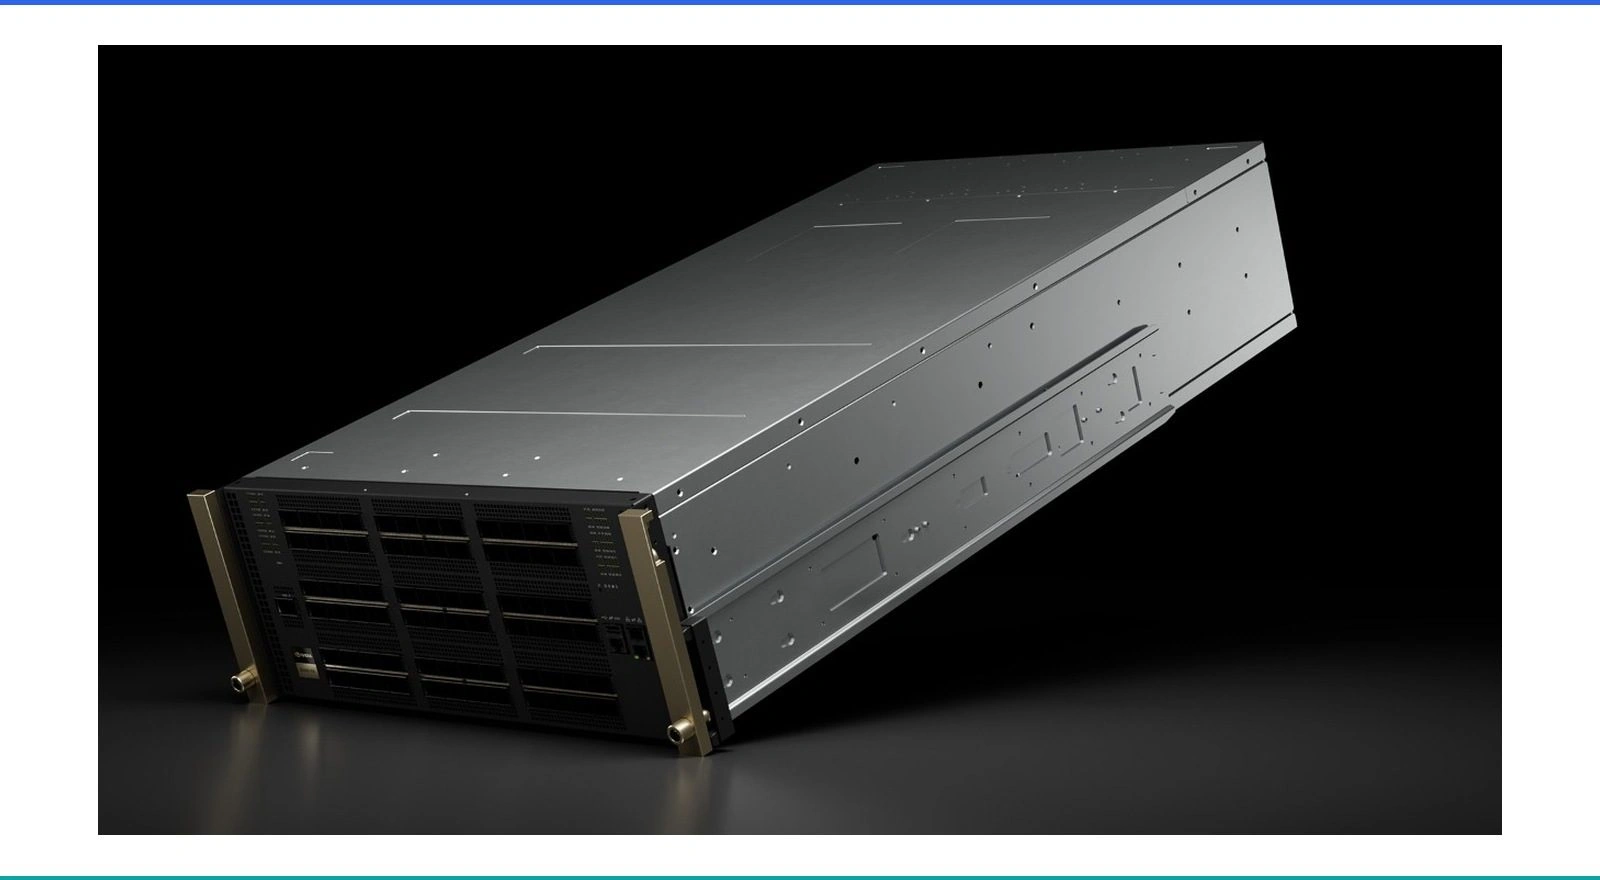
Flexible Billing
Pay-per-use, time-pack, and subscription billing models.
Revenue Sharing
Operate compute externally and share revenue by agreed ratio.
Operations Views & Illustrations
Data-driven operations decisions keep compute assets creating value.
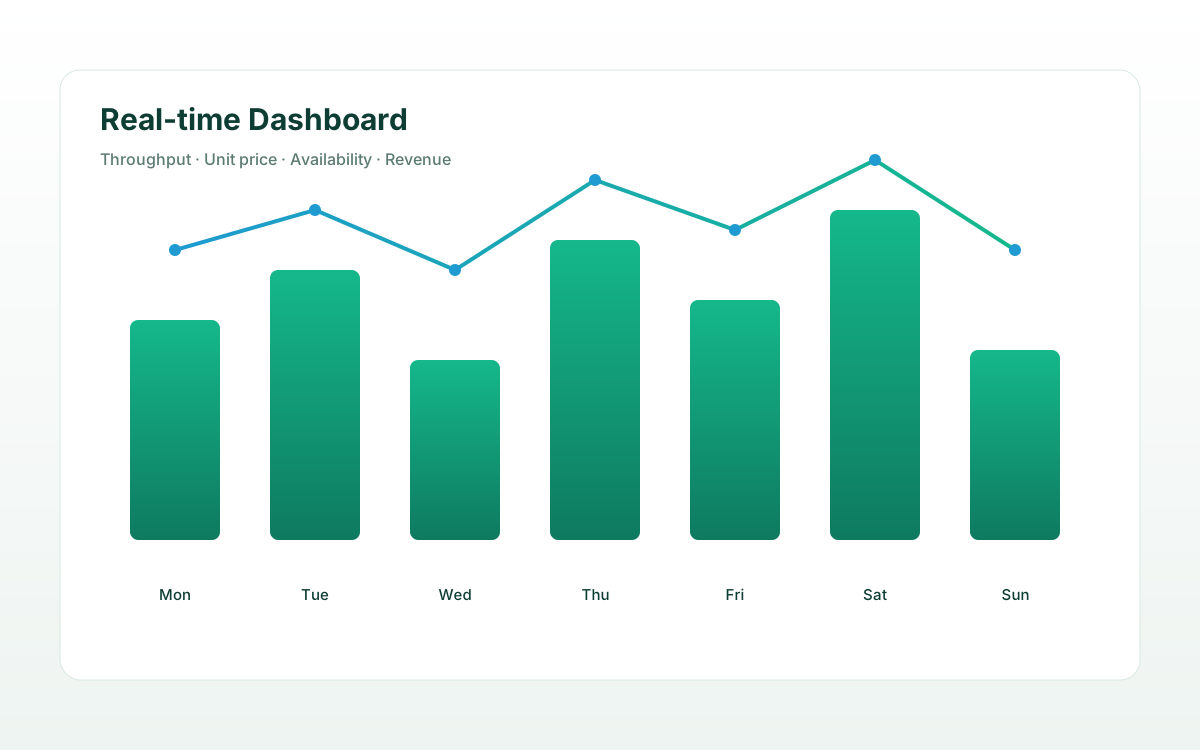
Real-time Dashboard
Throughput, unit price, availability, and revenue on one screen.
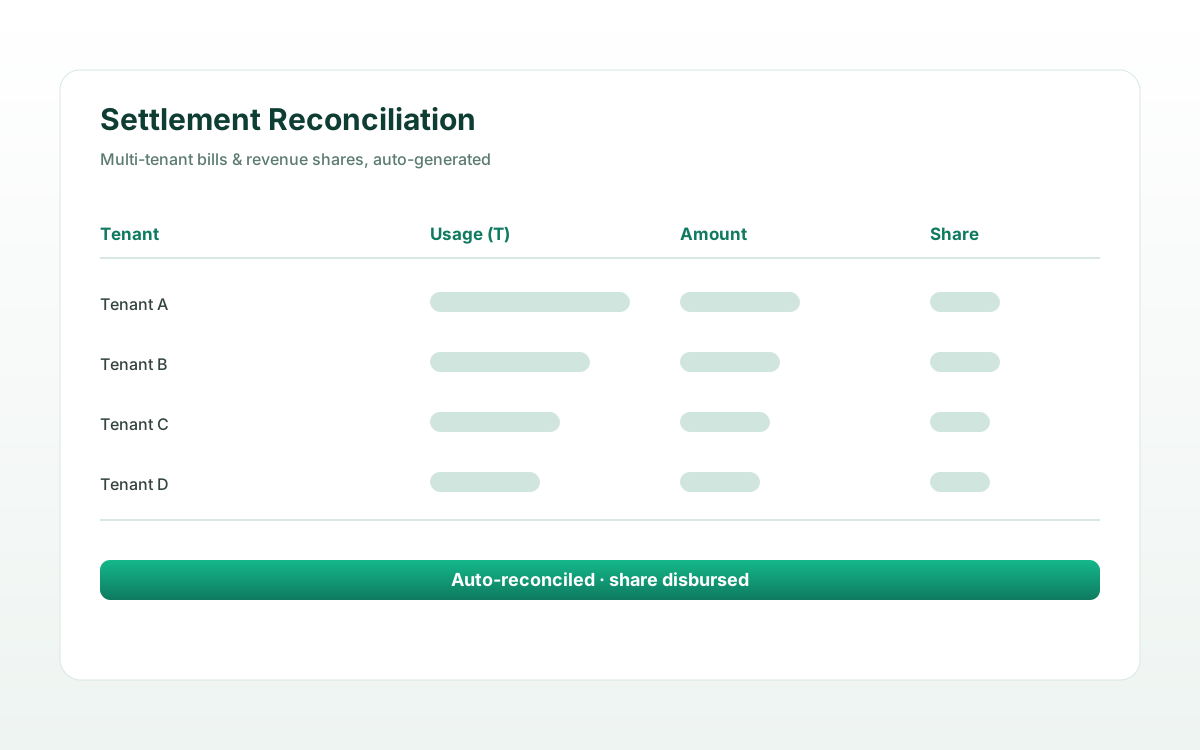
Settlement Reconciliation
Multi-tenant bills and revenue shares auto-generated to reduce manual work.
From blueprint to revenue
Whether building a new AI data center or operating existing compute, HYPEX AI delivers the right modular capabilities.